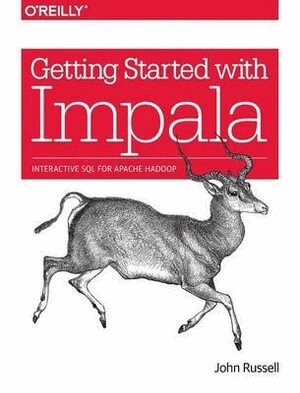
Getting Started with Impala Upplaga 1
- Upplaga: 1a upplagan
- Utgiven: 2014
- ISBN: 9781491905777
- Sidor: 110 st
- Förlag: O'Reilly Media
- Format: Häftad
- Språk: Engelska
Om boken
Learn how to write, tune, and port SQL queries and other statements for a Big Data environment, using Impala - the massively parallel processing SQL query engine for Apache Hadoop. The best practices in this practical guide help you design database schemas that not only interoperate with other Hadoop components, and are convenient for administers to manage and monitor, but also accommodate future expansion in data size and evolution of software capabilities. Ideal for database developers and business analysts, Getting Started with Impala includes advice from Cloudera's development team, as well as insights from its consulting engagements with customers. Learn how Impala integrates with a wide range of Hadoop components Attain high performance and scalability for huge data sets on production clusters Explore common developer tasks, such as porting code to Impala and optimizing performance Use tutorials for working with billion-row tables, date- and time-based values, and other techniques Learn how to transition from rigid schemas to a flexible model that evolves as needs change
Åtkomstkoder och digitalt tilläggsmaterial garanteras inte med begagnade böcker
Mer om Getting Started with Impala (2014)
I oktober 2014 släpptes boken Getting Started with Impala skriven av John Russell. Det är den 1a upplagan av kursboken. Den är skriven på engelska och består av 110 sidor. Förlaget bakom boken är O'Reilly Media.
Köp boken Getting Started with Impala på Studentapan och spara pengar.
Referera till Getting Started with Impala (Upplaga 1)
Harvard
Russell, J. (2014). Getting Started with Impala. 1:a uppl. O’Reilly Media.
Oxford
Russell, John, Getting Started with Impala, 1 uppl. (O’Reilly Media, 2014).
APA
Russell, J. (2014). Getting Started with Impala (1:a uppl.). O’Reilly Media.
Vancouver
Russell J. Getting Started with Impala. 1:a uppl. O’Reilly Media; 2014.
citeproc-js implements the Citation Style Language. (c) Frank Bennett. Licenser och källkod.